
By Jayoo Hwang, Vansh Ramani, and Shourya Vir Jain
A new hire's first day in an unfamiliar ERP is slow. A month later, they know the procedure and barely look at the interface. Most browser agents never get past day one. Ramain does.
- 79%
- Faster after learning
- 67%
- Fewer fresh tokens
- 885 → 438
- Model rounds
The experiment
We tested Ramain on an internal set of realistic long-horizon tasks. The autonomous agent completed every task without previous knowledge, but it did so slowly and with detours.
The cold baseline was about 6.3 minutes and 44 model rounds per task. We then let the platform learn from those successful trajectories in two rounds.
Round one: extract the workflow
Workflow extraction turns a successful trajectory into procedural guidance. The next run starts from the correct action sequence instead of discovering it again.
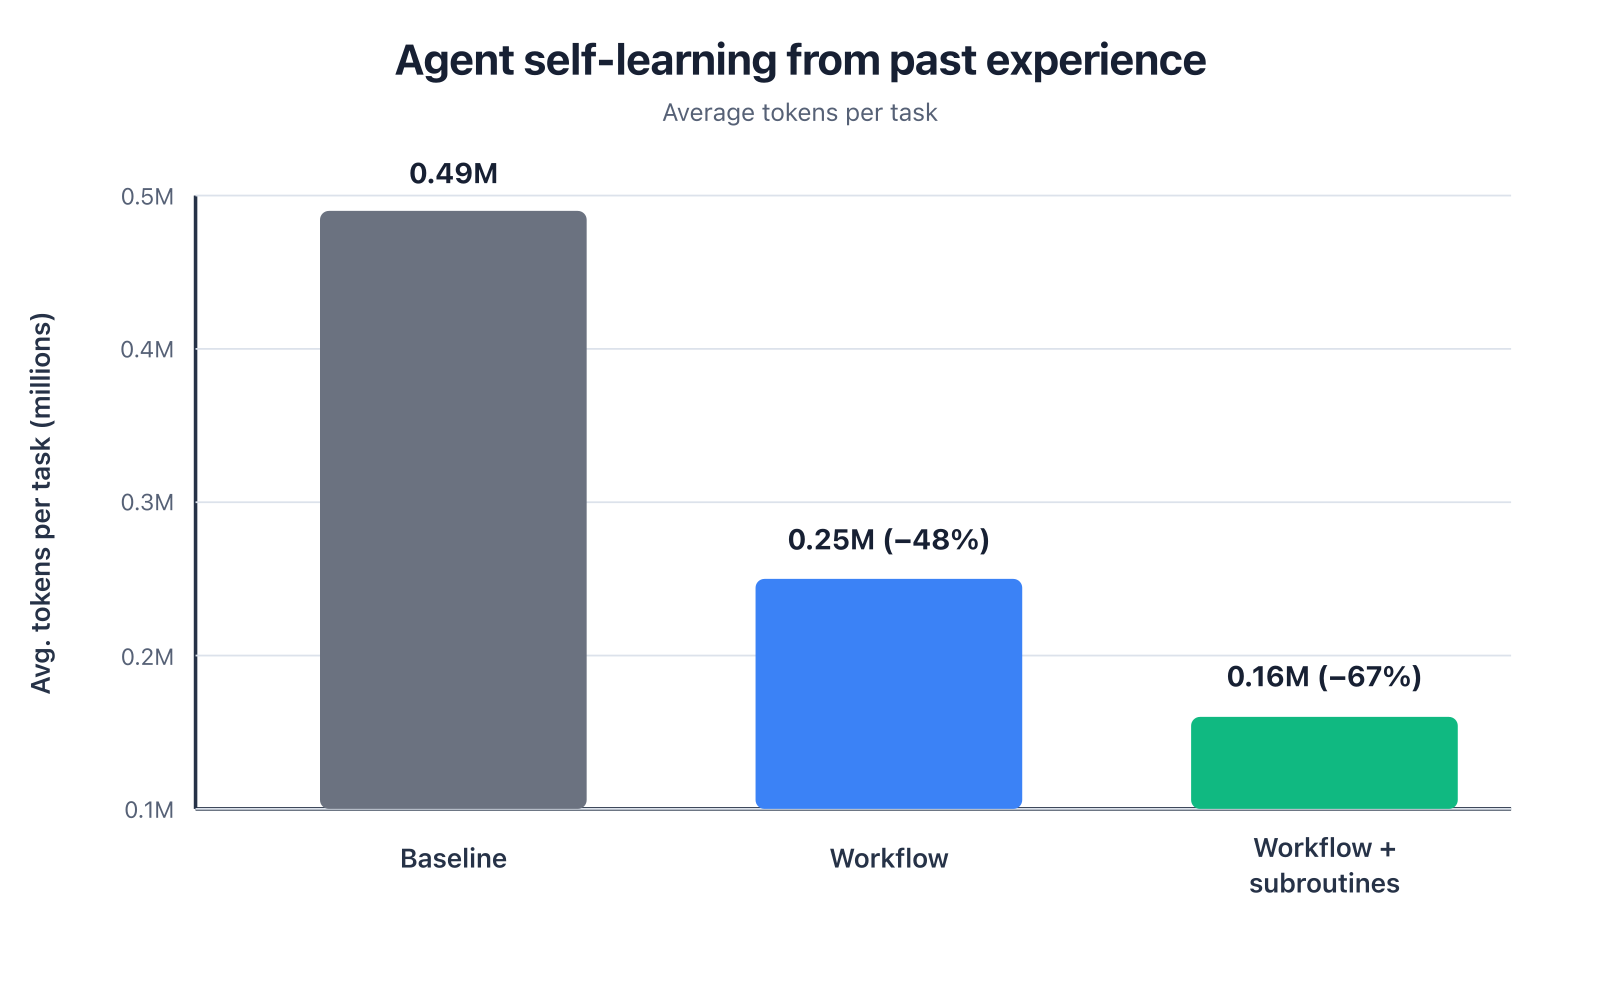
With the same tasks and model, wall time fell 68%, from 6.3 minutes to 2 minutes across the task set. Fresh input tokens fell by nearly half.
Round two: turn the procedure into muscle memory
An optimization agent read the trajectories and produced reusable scripts. These subroutines execute rote stretches programmatically without spending a model round.
Total model rounds fell from 885 to 438. Against the original baseline, the tasks ran 79% faster while using one third of the fresh input tokens.
Production performance compounds
Benchmarks measure first encounters, so cold-run numbers are a floor. In production, similar workflows run on similar portals every day.
The first deployed version is the least experienced version that will ever run. Every later run can start with more procedural knowledge than the one before.
Ramain learns from its own experience to become faster and cheaper every time a workflow repeats.
